Large-scale, high-quality multimodal demonstrations are essential for robot learning of contact-rich dexterous manipulation. While human-centric data collection systems lower the barrier to scaling, they struggle to capture the tactile information during physical interactions. Motivated by this, we present DexViTac, a portable, human-centric data collection system tailored for contact-rich dexterous manipulation. The system enables the high-fidelity acquisition of first-person vision, high-density tactile sensing, end-effector poses, and hand kinematics within unstructured, in-the-wild environments. Building upon this hardware, we propose a kinematics-grounded tactile representation learning algorithm that effectively resolves semantic ambiguities within tactile signals. Leveraging the efficiency of DexViTac, we construct a multimodal dataset comprising over 2,400 visuo-tactile-kinematic demonstrations. Experiments demonstrate that DexViTac achieves a collection efficiency exceeding 248 demonstrations per hour and remains robust against complex visual occlusions. Real-world deployment confirms that policies trained with the proposed dataset and learning strategy achieve an average success rate exceeding 85% across four challenging tasks. This performance significantly outperforms baseline methods, thereby validating the substantial improvement the system provides for learning contact-rich dexterous manipulation.
The human demonstration interface features a decoupled design comprising a fisheye camera, motion-capture gloves, high-resolution tactile sensors, and a T265 tracking camera. The robot execution platform utilizes an isomorphic perception architecture wherein the tactile sensors remain strictly consistent with those on the human demonstration interface.

To prevent frame loss and ensure tight spatiotemporal alignment across different modalities, we employ high-frequency buffering alongside a tactile-anchored synchronization strategy that involves downsampling and nearest-neighbor matching.

The dataset contains 2,400+ visuo-tactile-kinematic demonstrations across 40+ tasks in 10+ real-world environments.

Stage 1: A self-supervised framework aligns high-density tactile features with visual anchors utilizing a kinematics-Grounded encoder to learn spatially anchored representations. Stage 2: The pretrained encoders are subsequently integrated into an Action Chunking with Transformers (ACT) policy to map synchronized multimodal observations to multi-step action sequences for contact-rich dexterous manipulation.

Deployment experiments are conducted across four representative tasks to evaluate real-world performance: pipetting, whiteboard erasing, pen insertion, and fruit collection.
The dexterous hand precisely regulates pinch force to operate a flexible rubber bulb, testing the high-sensitivity force control performance of the system.
This requires the end-effector to maintain constant contact pressure along dynamic trajectories, evaluating force compliance and stability during dynamic interactions.
Grasping and inserting small markers, involving stable grasping and in-hand manipulation capabilities.
Operating on heterogeneous objects with varying stiffness to verify adaptability to different physical properties.
@misc{chen2026dexvitaccollectinghumanvisuotactilekinematic,
      title={DexViTac: Collecting Human Visuo-Tactile-Kinematic Demonstrations for Contact-Rich Dexterous Manipulation},
      author={Xitong Chen and Yifeng Pan and Min Li and Xiaotian Ding},
      year={2026},
      eprint={2603.17851},
      archivePrefix={arXiv},
      primaryClass={cs.RO},
      url={https://arxiv.org/abs/2603.17851},
}Extending DexViTac to bimanual visuo-tactile-kinematic demonstration collection.
* Corresponding author
From single-hand demonstrations to coordinated bimanual capture.
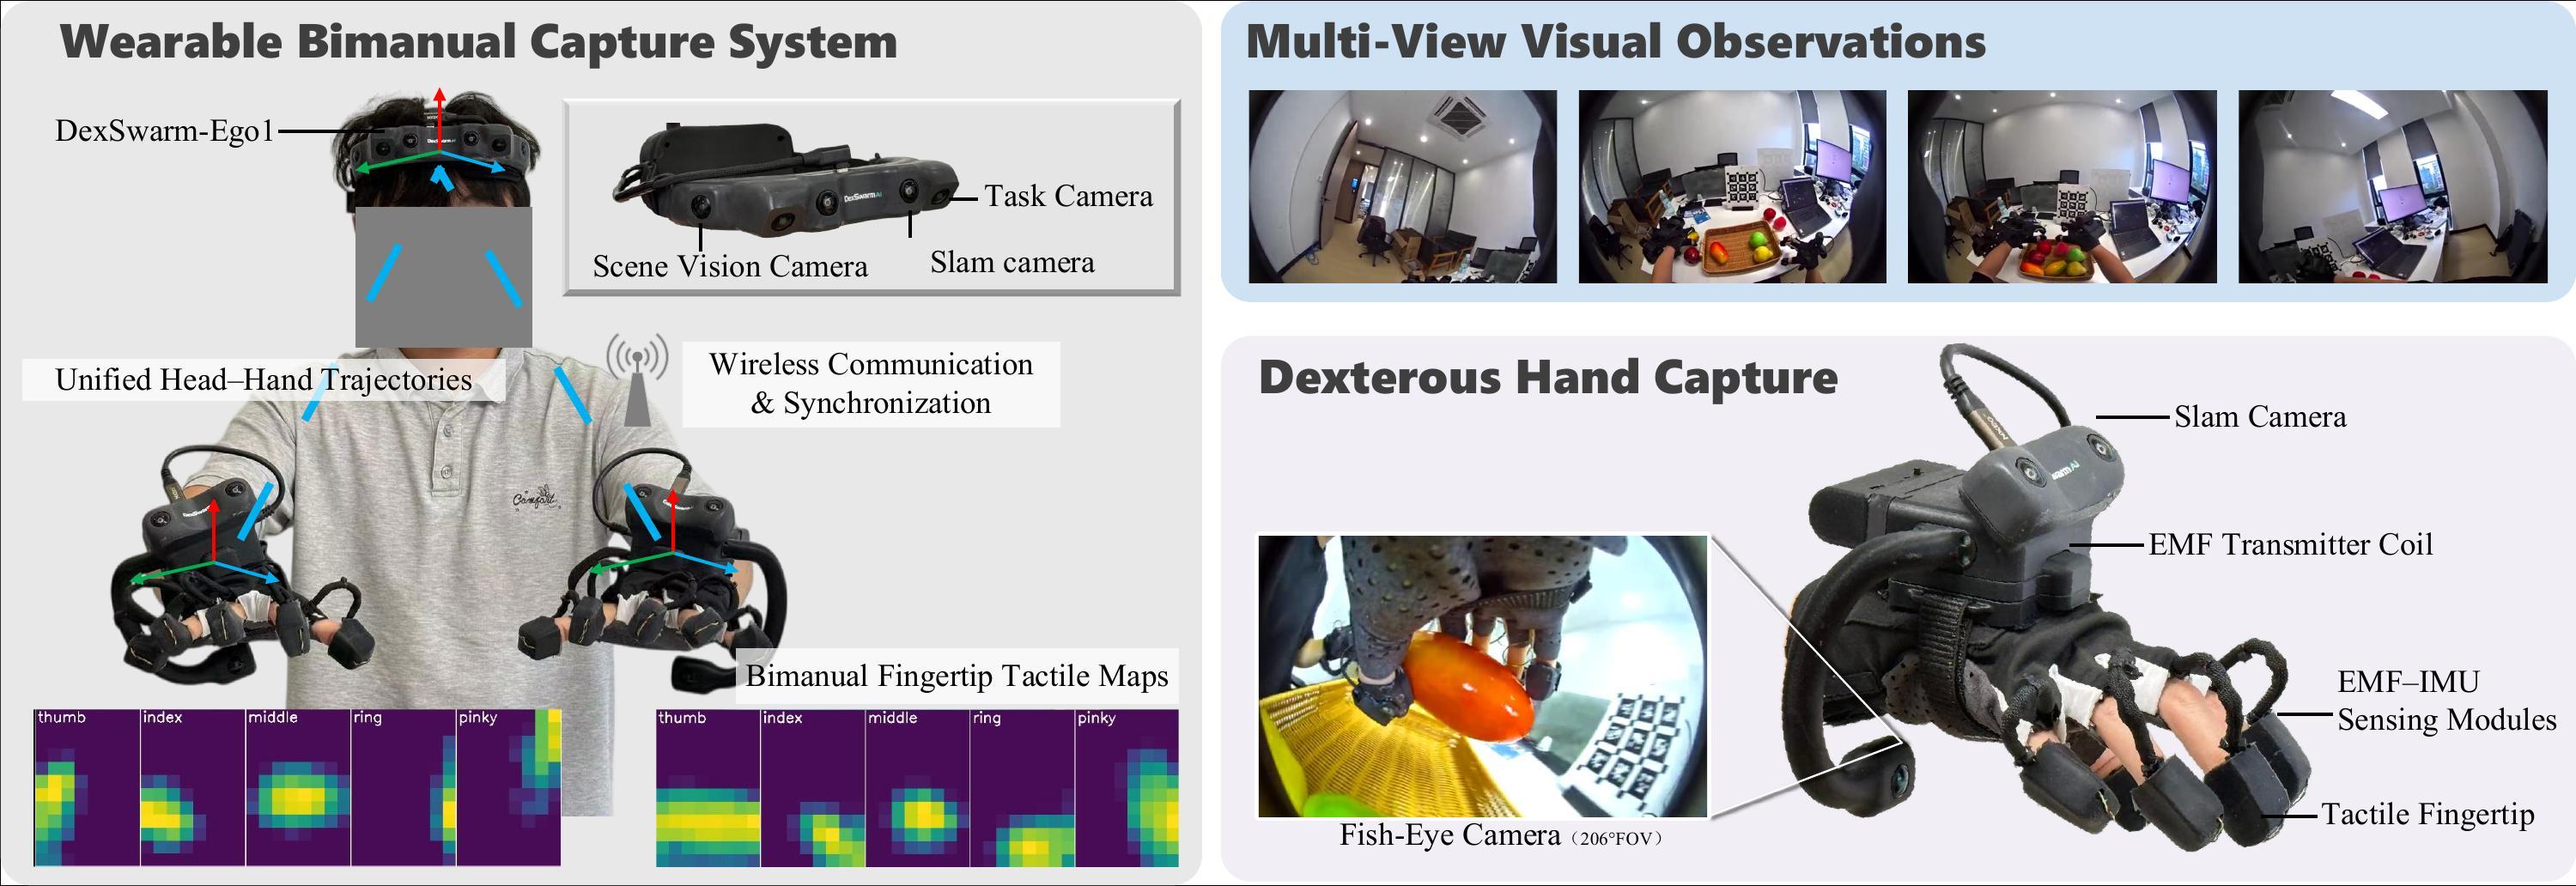
Robot-free demonstration collection can broaden access to contact-rich dexterous manipulation, but bimanual acquisition requires contact, finger articulation, and wrist motion to share a consistent spatial and temporal context. We present DexViTac++, a portable system extending DexViTac to two instrumented hands and an egocentric head unit. The interface integrates magnetic–inertial hand tracking, wrist vision, fingertip tactile sensing, and three stereo–inertial tracking streams, with a complete hand unit weighing 240 g. An offline reconstruction pipeline registers independently estimated trajectories through a common calibration target and exports synchronized head-relative and inter-hand poses. The system builds on DexViTac's kinematics-grounded tactile learning formulation and provides a unified collection representation for downstream bimanual learning. This paper presents the collection system and reconstruction workflow; quantitative evaluation of the new hardware and bimanual policies is left to future work.
DexViTac++ extends DexViTac to two DexSwarm UMI hand units and a DexSwarm EGO head unit. Developed at DexSwarm AI, the integrated hardware replaces the original commercial glove and T265 modules while retaining the vision, touch, and kinematics modalities.
Wrist cameras capture local hand–object interactions. The EGO head unit adds first-person workspace observations and its own stereo–inertial pose stream.
Tactile sensors on both hands record finger contact alongside images and articulation, preserving the contact context of bimanual demonstrations.
A hand-dorsum electromagnetic transmitter and fingertip electromagnetic–inertial modules support 21-DoF capture per hand, with cable-free operation.
Each 240 g hand unit includes cameras, tactile sensors, and battery, and operates without an external host or power cable.
| Component | DexViTac | DexViTac++ |
|---|---|---|
| Collection interface | Single instrumented hand | Two hands and an EGO head unit |
| Finger capture | Commercial glove, 19 DoF | In-house magnetic–inertial, 21 DoF/hand |
| Body tracking | T265-based wrist tracking | Three stereo–inertial trajectories |
| Contact | Fingertip tactile measurements | Fingertip tactile measurements |
| Spatial export | Single-hand trajectory | Registered head-relative and inter-hand poses |
| Connectivity | Wired operation | Cable-free wireless operation |
This comparison summarizes reported collection configurations rather than a controlled benchmark. These interface specifications do not establish superior robot-policy performance or tracking accuracy.
| System | Capture DoF | Weight (g) | Tracking | Tac. | Bi. | In-the- wild | No ext. tracking | Link |
|---|---|---|---|---|---|---|---|---|
| UMI | 1 | 780† | VIO | × | ✓ | ✓ | ✓ | Local |
| DexCap | NRa | NR | VIO | × | ✓ | ✓ | ✓ | Wired |
| DexWild | NRa | NR | Markerb | × | ✓ | ✓ | × | NR |
| DexUMI | 6/12 | 850† | VIO | ✓ | × | NR | ✓ | NR |
| DEXOP | 12/9/7 | >1000† | FKc | ✓ | ✓ | ✓ | ✓ | Wired |
| DexEXO | 6 | >1000† | AR | × | × | ✓ | ✓ | NR |
| RealDexUMI | 6 | 680d | NR | ✓ | ✓ | ✓ | NR | NR |
| DexViTac | 19 | <600† | VIO | ✓ | × | ✓ | ✓ | Wired |
| DexViTac++ | 21 | 240e | VIO | ✓ | ✓ | ✓ | ✓ | Wireless |
Definitions. Capture DoF excludes wrist pose; slash-separated values denote variants. Tac.: tactile sensing. Bi.: bimanual collection. NR: not established in this comparison. In-the-wild: reported operation outside a fixed robot workspace. VIO: visual–inertial odometry. FK: forward kinematics. AR: smartphone AR tracking.
Tracking and connectivity. No external tracking means no external base station or off-hand camera observing the hand. Wired requires a host or power cable; Wireless denotes cable-free wireless communication; Local denotes onboard operation. Checkmarks and crosses refer to the compared configuration, not all possible variants.
a Keypoint representation; capture DoF unspecified. b Marker tracking with a separate camera. c Requires the AirExo-2 arm exoskeleton.
† Weights reproduced from RealDexUMI; included components may differ. d Reported by RealDexUMI. e Complete hand unit, excluding the 252 g head unit. These weights are not a controlled comparison with matched component inclusion.
Three independently tracked devices initially produce trajectories in unrelated local maps. DexViTac++ registers these maps to a common calibration target, then associates the streams in time to preserve the geometry between the head and both hands.
An offline ORB-SLAM3-based stereo–inertial estimator processes each device’s calibrated stereo images and IMU measurements.
All three devices observe a stationary 3 × 3 AprilGrid of 50 mm tags during calibration. Robust transform aggregation relates each local map to the board frame.
Hand poses are resampled at head timestamps, producing synchronized head-relative and inter-hand transforms alongside the head’s own motion.
Acquisition uses Tic-based wireless synchronization; spatial registration is a separate operation. DexSwarm Studio supports playback, inspection, and export, with timestamps, calibration metadata, and original measurements retained for downstream retargeting.
Temporal association uses linear translation interpolation and spherical linear interpolation of rotation. Samples are skipped when either endpoint is more than 50 ms from the reference timestamp; this threshold is an association criterion, not a measured synchronization accuracy.
DexViTac++ builds on the original DexViTac formulation: tactile features are conditioned on hand articulation, aligned with visual features through contrastive pretraining, and used by an ACT policy for action-chunk prediction. Updated hardware still requires its own hand-to-robot mapping and wrist calibration.
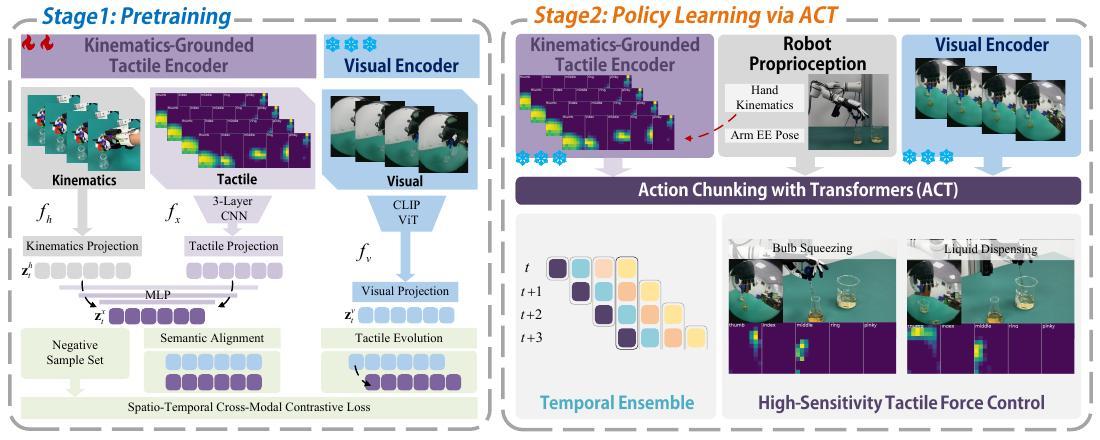
The original system collected more than 2,400 demonstrations across over 40 tasks and more than 10 environments. Evaluation on a RealMan RM-65 arm and an Inspire RH56DFTP hand used 30 trials per task.
| Task | Success rate |
|---|---|
| Pipetting | 83.3% |
| Whiteboard erasing | 86.7% |
| Marker insertion | 80.0% |
| Fruit collection | 93.3% |
| Mean | 85.8% |
DexViTac++ presents the collection interface and offline reconstruction workflow. Quantitative evaluation of the new hardware and bimanual policies remains future work, including relative-pose drift, synchronization error, demonstration yield, and policy transfer across operators and tasks.
Reconstruction depends on stereo–inertial initialization, calibrated extrinsics, and a stationary calibration target. Independent drift can affect relative geometry; interpolation cannot recover missing measurements or unknown clock offsets. Human-to-robot differences in hand geometry, contact, and camera viewpoint also remain.
The following resources belong to the predecessor and support the learning foundation described above.
@misc{chen2026dexvitacplus,
  title={DexViTac++: A Bimanual Visuo-Tactile-Kinematic Demonstration Collection System},
  author={Xitong Chen and Ziqiang Liu and Min Li and Zhouping Yin},
  year={2026},
  note={Manuscript},
  url={https://xitong-c.github.io/DexViTac/dexvitac-plus.html}
}